Skip to content

Blog

Pentaho BI integration with Active Directory

This is a quick guide of how to integrate the Pentaho BI platform with Active Directory. It has been tested on version 5 and 6, it's not yet tested on version 7.

The first file that has to be modified is biserver-ce\security.properties where we have to specify that we want to use LDAP authentication:

provider=ldap

Then we have to modifiy the file biserver-ce\pentaho-solutions\system\applicationContext-security-ldap.properties which has to be updated with the actual Active Directory parameters.

  • our domain name is example.com and our domain controllers will answer with example.com
  • our user with read permissions on the AD schema is browsingad@example.com
  • we have to create a OU Example Users\Groups\Pentaho Roles where we will create our groups (for example Pentaho Administrators, Pentaho Read Only, Pentaho Dashboards etc.) with a proper description

This is how the file will look like:

contextSource.providerUrl=ldap\://example.com\:389/DC\=example,DC\=com
contextSource.userDn=CN\=browsingad,OU\=Example Users,DC\=example,DC\=com
contextSource.password=password

userSearch.searchBase=OU=Example Users
userSearch.searchFilter=(samaccountname\={0})

populator.convertToUpperCase=false
populator.groupRoleAttribute=description
populator.groupSearchBase=OU\=Pentaho Roles,OU\=Groups,OU\=Example Users
populator.groupSearchFilter=(member\={0})
populator.rolePrefix=
populator.searchSubtree=true

allAuthoritiesSearch.roleAttribute=description
allAuthoritiesSearch.searchBase=OU\=Pentaho Roles,OU\=Groups,OU\=Example Users
allAuthoritiesSearch.searchFilter=(objectClass\=group)

allUsernamesSearch.usernameAttribute=samaccountname
allUsernamesSearch.searchBase=OU\=Example Users
allUsernamesSearch.searchFilter=(objectClass\=Person)

adminRole=cn\=Pentaho Administrators,OU\=Pentaho Roles,OU\=Groups,OU\=Example Users
adminUser=cn\=admin.user,OU\=IT Staff,OU\=Example Users

Finally we can modify the file \biserver-ce\pentaho-solutions\system\pentaho.xml to hide test users:

<login-show-users-list>false</login-show-users-list> 
<login-show-sample-users-hint>false</login-show-sample-users-hint>

and also our logo:

biserver-ce/pentaho-solutions/system/common-ui/resources/themes/images/puc-login-logo.png

Scheduling Kettle Jobs

Pentaho Data Integration is an open source tool that provides Extraction, Transformation, and Loading (ETL) capabilities. While it's an essential DWH tool, I use it quite a lot also as an integration tool, where it performs well.
Pentaho Kettle

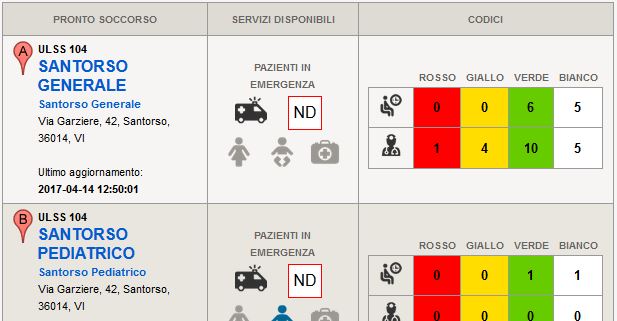
For example, we use it to populate a table with the current load of our emergency rooms, then a Perl application will publish the contents of the table in JSON format, and finally a Web Application and an Android Application read the content of the JSON and shows the data to the users formatted in a nice way:
First Aid

We also use it to transfer historical data from legacy applications to the new ones. To distribute patients data between different softwares of different vendors. To do quality checks on our tables, and generate automatically emails with alarms. Or to fetch XML or Excel files we get from web services, and integrate the contents into our live systems. To prepare monthly TXT or Excel or XML extractions.

All those tasks are managed by some jobs that calls multiple transformations, but I have to schedule those jobs somehow. And I want to keep track of which jobs are run, how long they took to execute, which ones failed.

But how's an effective way to do all of this?

This is what I am using, and I find it very flexible and pretty elegant.

Windows Scheduler

I wanted to use the standard Windows Scheduler, not the Pentaho scheduler. For Linux machines the procedure is very similar. First of all I have created a StartJob.cmd batch file, that accepts only one parameter: the job to be executed. Here's how it looks like:

@echo off

set kitchen="D:\Pentaho\kettle\data-integration\kitchen.bat"

set repository="Repository ULSS4"
set repository_user=username
set repository_pass=password

set job_dir="/Updates"
set job_name=%1
set log="D:\Script\Spoon\log\"%2".log"

%kitchen% /rep:%repository% /user:%repository_user% /pass:%repository_pass% /dir:%job_dir% /job:%job_name% /level:Basic >> %log%

We can start a job very simply with the following command:

C:\>StartJob.CMD "job_updates_15min"

which is more convenient than calling the kitchen.bat batch file directly since most parameters are pre-configured already.

I then scheduled a list of jobs to be executed at different intervals, e.g.

  • job_updates_daily
  • job_updates_1h
  • job_updates_mondays
  • job_updates_1th_month

this has to be configured only once, then we won't touch the task scheduler anymore.

Each of those jobs will contain a list of sub-jobs that will be executed (e.g. job_update_json, job_send_email, ...) and that will perform some specific tasks.

The Scheduled Jobs

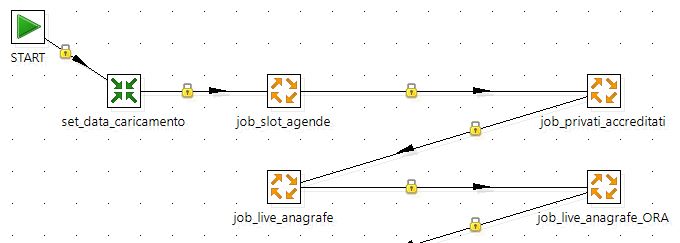
Every scheduled job (daily, 1h, 15min, etc.) is structured this way:

  • first we define the starting point for job execution
  • then we execute a transformation that sets in a variable the current date (for logging reasons)
  • finally, we insert in sequence all the jobs we actually want to execute (e.g. job_update_json, job_send_email, ...)

this is how it looks like:
Daily Job

make sure that connections are black (unconditional), so a failing job won't prevent the following jobs to be executed.

Whenever I prepare a new job and I want to schedule it daily, I will add this new job to the job_updates_daily outer job. And whenever I change my mind and I want to execute it hourly, I will just remove it from the job_updates_daily and add it to the job_updates_1h job.

The Log Table

The main goal of the log table is to keep track of all tasks (jobs/transformations) that have been executed, when they have been executed, how long they took, how many rows were updated, which ones failed.

The basic table structure is defined this way (in PostgreSQL syntax):

create table log_updates (
  id serial primary key,
  data_esecuzione varchar(20),
  flagtipotabella varchar(20),
  nometrasformazione varchar(40),
  dtiniziocaricamento timestamp,
  dtfinecaricamento timestamp,
  esitocaricamento int,
  read int,
  written int,
  updated int
  unique (data_esecuzione, flagtipotabella, nometrasformazione)
)

and it will look like:

id data_esecuzione flagtipotabella nometrasformazione dtiniziocaricamento dtfinecaricamento esitocaricamento read written updated
1 2017-04-14 DWH dim_doctors_update 2017-04-14 15:00:01 2017-04-14 15:03:35 0 743 3 86
2 2017-04-14 Web Apps update_ps_json 2017-04-14 15:03:37 2017-04-14 15:05:54 2
3 2017-04-14 Web Apps update_patients 2017-04-14 15:05:59 1

here we can see that:

  • the task DWH / dim_doctors_update was executed successfully (esitocaricamento=0)
  • the task Web Apps / update_ps_json ended up with an error (esitocaricamento=2)
  • the task Web Apps / update_patients didn't finish yet (maybe it's still running or maybe it hang...).

Adding a new job on the log table

Whenever a new job starts, a single row with esitocaricamento=1 will be generated:

data_esecuzione flagtipotabella nometrasformazione esitocaricamento dtiniziocaricamento
2017-04-14 DWH dim_doctors_update 1 2017-04-14 15:00:01

and an Insert/Update step using the lookup keys (data_esecuzione, flagtipotabella, nometrasformazione) will add it to the logs table (or will reset the row if the same task will be performed multiple times on the same day)

Updating the job status

Then, whenever the task end succesfully, another row will be generated. with the same lookup keys ('2017-04-14', 'DWH', 'dim_doctors_update') but an updated status esitocaricamento=0 and an updated current_timestamp as the end datetime (and eventually the number of rows read, written and updated).

I'm using an Insert/Update step also here, with the same lookup keys, so the status will be updated from 1 to 0 (great!), the datetime_start column will be left untouched but the datetime_end, read, written, updated columns will be updated.

Whenever the task end unsuccesfully, we are doing the same but we will update the status from 1 to 2.

If the tast is still running, the status will be 1. This solves a common logging problem - first we insert a row with the status "executing", then the status will be updated to "completed" once we are sure that the task ended properly.

Setting the current date in a variable

This task is for logging pourposes. We are going to run a query that returns the current date:

select current_date as currentdate from dual

and save in the data_caricamento variable. Here's how it will look like:
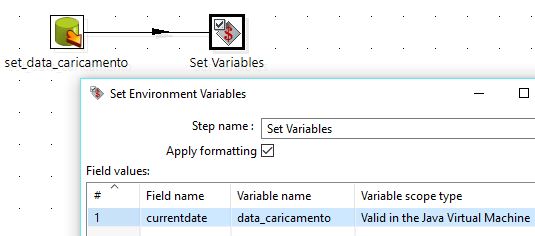
Set Load Date

(here I assume that having a daily log is fine: only the last execution of the day will be logged, previous ones will be overwritten)

How a standard Job will look like

All standard jobs that performs a specific task will share a similar structure:

  • we define a starting point
  • then we will call the transformation general_log_start (it puts on the log table a row informing us that that the job has started)
  • then we call one or more transformations (or sub-jobs) that will perform the taks we need, eg. import some data, update a table, etc.
  • when everything is okay (green connections) we will call the general_log_end transformation called general_log_end OK
  • when anything goes wrong (red connections) we will call the general_log_end transformation called general_log_end KO

and here's how it will look like in Kettle:
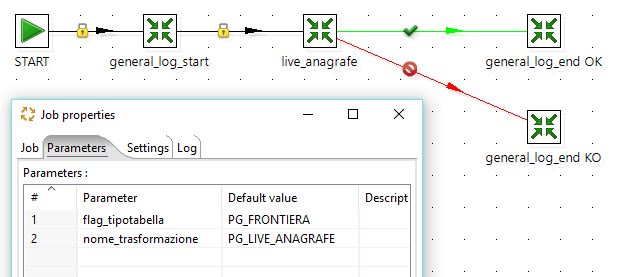
Standard Job

as we can see from the picture above, I have defined two parameters:

  • flagtipotabella eg. DWH, Web App, Other
  • nometrasformazione eg. job_update_patients, job_send_email

those parameters will be used for logging purposes by the general_log_start and general_log_end jobs.

General Log Start

This task will insert a new row on the logs table with the following informations:

  • data_caricamento which is the current date time of the shceduled task
  • flagtipotabella, taken from the parameters of the outer job
  • nometrasformazione, taken from the parameters of the current job
  • the current date time, which will be the start date/time
  • esitocaricamento=1, the task has been started
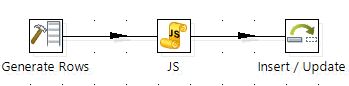
General Log Start

Here's how the generate rows step will look like:
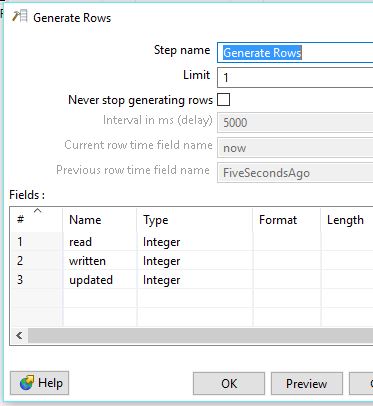
Generate Rows

Here's a JavaScript step that will get the parameters from the outer job:

var dtcaricamento = getVariable("data_caricamento","");
var nometrasformazione = getVariable("nome_trasformazione","no");
var flagtipotabella = getVariable("flag_tipotabella","no");
var dtiniziocaricamento = new Date();
var dtfinecaricamento;
var esitocaricamento = 1

and here's how the Insert/Update step will look like:
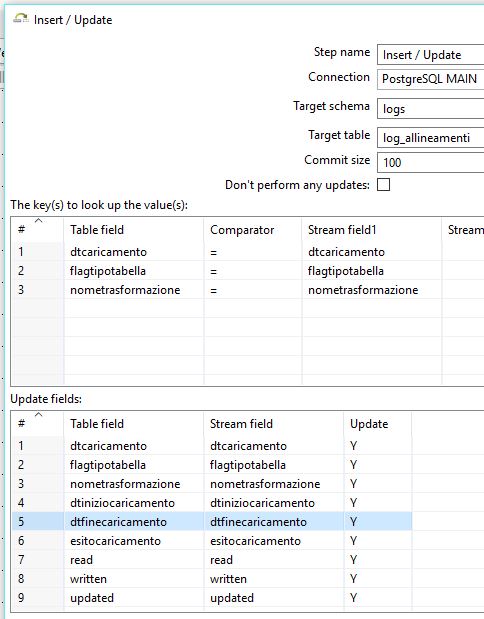
Insert/Update

General Log End

The general log end is very similar to the general log start, but it will either mark the task as Completed (esitocaricamento=0) or Failed (esitocaricamento=2). The parameter esitocaricamento has to be defined as a parameter (right click -> Edit job entry -> parameters).
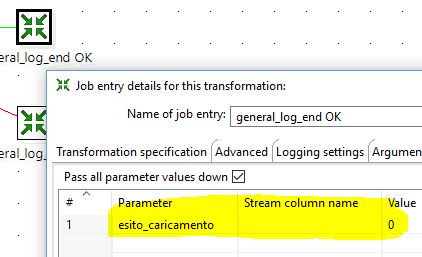
Insert/Update

only the JavaScript code is different:

var dtcaricamento = getVariable("data_caricamento","");
var nometrasformazione = getVariable("nome_trasformazione","");
var flagtipotabella = getVariable("flag_tipotabella","");
var esitocaricamento = getVariable("esito_caricamento","");

var read = getVariable("LINES_READ","") | "";
var written = getVariable("LINES_WRITTEN","") | "";
var updated = getVariable("LINES_UPDATED","") | "";

setVariable("read", null, "p");
setVariable("written", null, "p");
setVariable("updated", null, "p");

var dtfinecaricamento;

if (esitocaricamento == '0') {
  dtfinecaricamento = new Date();
} else {
  dtfinecaricamento = null;
}

Transformation

The transformation will just perform the actual task, something like reading data from one table, perform some calculations, writing the output to another table.

The interesting part here is to use an Output Step Metrics to get the number or rows read, written, updated and make it available to the outer job where the General Log End transformation will save those values in the logs table:
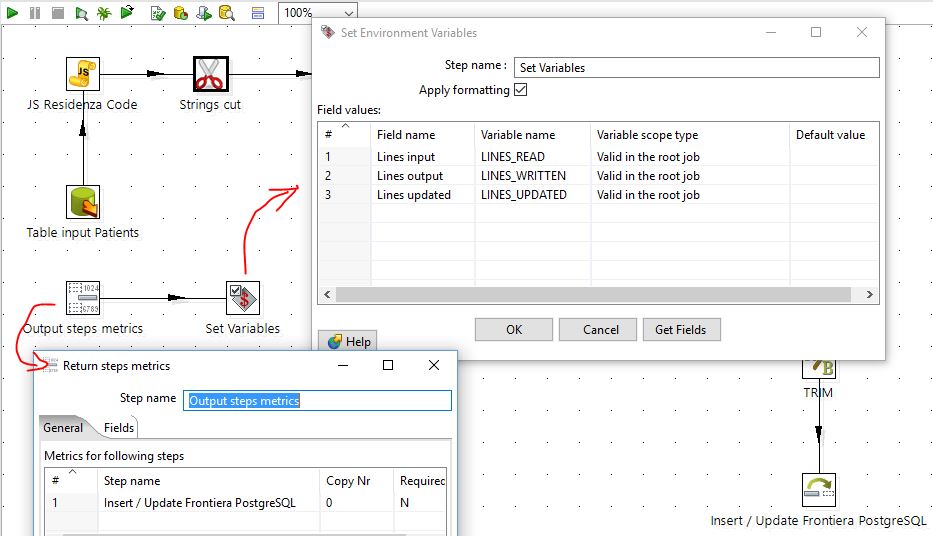
Insert/Update

Conclusion

Setting up some scheduled task using this technique requires some more work the first time, but once the system is properly set up managing scheduled tasks becomes fun!
MySQL and Full Outer Join

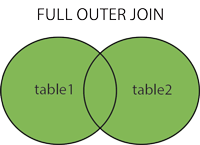
In SQL, a full outer join is a join that returns all records from both tables, wheter there's a match or not:

Full Outer Join

unfortunately MySQL doesn't support this kind of join, and it has to be emulated somehow. But how?

In SQL it happens often that the same result can be achieved in different ways, and which way is the most appropriate is just a matter of taste (or of perormances).

But this time the question is a little controversial, even on StackOverflow not everyone agrees and the solution marked as correct isn't actually the correct one.

Suppose we have the following tables:

Customers:

company_id name
1 Abc Company
2 Noise Inc.
3 Mr. Smith

Partners:

company_id name
2 Noise Inc.
4 The Pages

a full outer join would be written as:

select
  c.name, p.name
from
  customers c full outer join partners p
  on c.company_id = p.company_id

and the expected result is:

name name
Abc Company
Noise Inc. Noise Inc.
Mr. Smith
The Pages

to get the same result we have to combine a left outer join query:

select c.name, p.name
from
  customers c left join partners p
  on c.company_id = p.company_id

with a right outer join query:

select c.name, p.name
from
  customers c right join partners p
  on c.company_id = p.company_id

(the right join is quite uncommon because it's more difficult to read, and is equivalent to a left join with the order of the tables switched).

We could combine both queries with an UNION ALL clause, but this would return some duplicates (all rows where the join succeeds will be returned twice).

We could then use an UNION clause which will remove duplicates, but it will fail if one of the table has no primary key or unique constraints, or if the selected columns are not unique.

We could also use a different approach:

select c.name, t.name
from
  (select company_id from customers UNION
   select company_id from partners) n
  left join customers c on n.company_id = c.company_id
  left join partners p on n.company_id = p.company_id

which is often a good solution, but would fail if we allow the company_id to be NULL in one or both tables (a full outer join will return those rows, while the previous one won't).

The most general solution is this:

select c.name, p.name
from
  customers c left join partners p
  on c.company_id = p.company_id

union all -- don't remove duplicates

select c.name, p.name
from
  customers c right join partners p
  on c.company_id = p.company_id
where
  c.company_id is null

duplicates, if already present on the source tables, won't be removed. And the anti-join pattern on the second query assures that we are not introducing new duplicated rows.

Tiles Page

Cruscotto

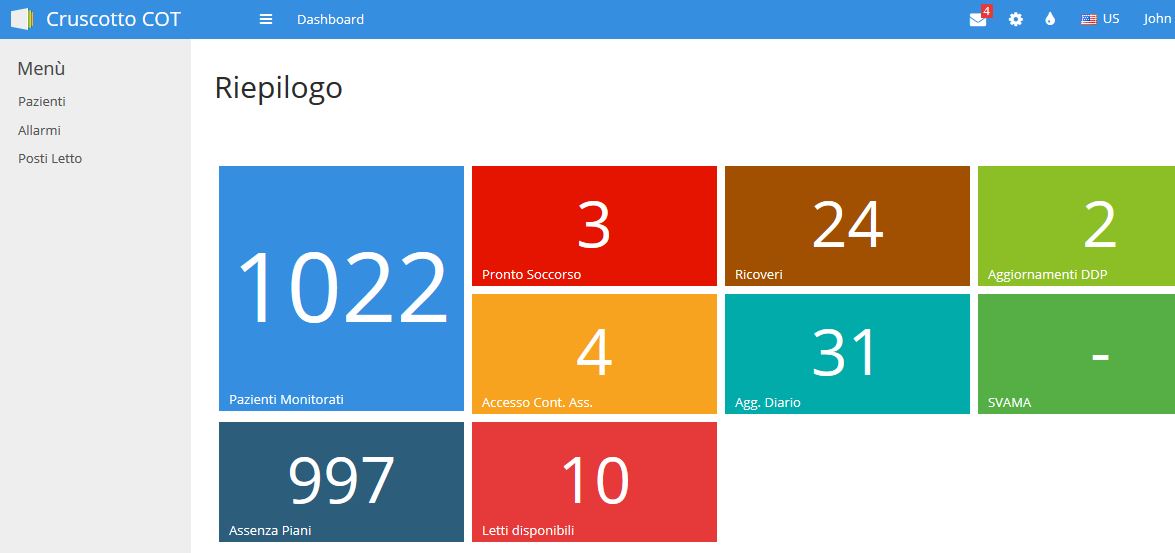
For my new application, I had to develop a summary page with all alarms in a single location: a tiles page is perfect for this purpose!

Of course, data has to be fetched using AJAX, however I didn't have a tiles module ready so this was the right moment to start developing one!

A tiles page is implemented like an unordered list:

<ul class="tiles">
  <li class="blue high long">
    <a href="pazienti_cot">
      <span class='count'></span>
      <span class='name'>Pazienti Monitorati</span>
    </a>
  </li>
  <li>
    ...
  </li>
</ul>

I just added a data-ajax-source data column on the ui tag (here's where we will fetch the counts) and a data-value that specifies the row where to get the counts. The AJAX data source will be in the same format as a datatables data source (because I'm lazy and I can reuse the same module hehe):

{
    "aaData":[
      ["PAZIENTI","1021"],
      ["TERR-RICOVERO","1"],
      ["TERR-ASSENZAPIANI","997"],
      ["OSP-DDP","5"],
      ["TERR-AGGDIARIOCA","30"],
      ["OSP-RICOVERO","24"],
      ["OSP-PS","4"],
      ["TERR-ACCESSOCA","5"],
      ["LETTI","10"]
    ],
    "iTotalRecords":"9",
    "iTotalDisplayRecords":"9",
    "sEcho":null
}

The tiles widget will be called as this:

  tiles-widget.mi,
    tiles => {
      json => "json/riepilogo.json",
      columns => [
        { caption => 'Pazienti Monitorati', value => 'PAZIENTI',          class => 'blue high long', href => 'pazienti_cot' },
        { caption => 'Pronto Soccotso',     value => 'OSP-PS',            class => 'red long',       href => '#' },
        { caption => 'Ricoveri',            value => 'OSP-RICOVERO',      class => 'brown long',     href => '#' },
        { caption => 'Aggiornamenti DDP',   value => 'OSP-DDP',           class => 'lime long',      href => '#' },
        { caption => 'Accesso Cont. Ass.',  value => 'TERR-ACCESSOCA',    class => 'orange long',    href => '#' },
        { caption => 'Agg. Diario',         value => 'TERR-AGGDIARIOCA',  class => 'teal long',      href => '#' },
        { caption => 'SVAMA',               value => 'TERR-SVAMA',        class => 'satgreen long',  href => '#' },
        { caption => 'Assenza Piani',       value => 'TERR-ASSENZAPIANI', class => 'satblue long',   href => '#' },
        { caption => 'Letti Disponibili',   value => 'LETTI',             class => 'lightred long',  href => 'letti_cot' },
      ]
    }
that will create a tiles html structure like the one above:

            <ul class="tiles" data-ajax-source="{json} %>">
% foreach my $box (@{$.tiles->{columns}}) {
               <li class="{class} %>" data-value="{value} %>">
                <a href="{href} %>">
                  <span class='count'></span>
                  <span class='name'>{caption} %></span>
                </a>
              </li>
% }
            </ul>

then the magic starts in the sentosa.js module:

function init_tile(tile) {
    $.getJSON( tile.attr("data-ajax-source"), function( data ) {
        // create an hash from the json aaData
        var a = data["aaData"];
        var h = {};
        for (var i=0; i< a.length; i++) {
            h[ a[i][0] ] = a[i][1];
        };
        // loop through all elements, and set data from the hash
        // (yes, I could directly read aaData and put it inside the html... but I also want to put - where data is not avaliable, so I have to use an hash first)
        $("li", tile).each(function () {
            $('span.count', this).text(h[$(this).attr("data-value")] || '-');
        });
    });
}

okay, this "init" will load the JSON, parse it in a map data structure, then loop through each li element and put the value accordingly to the data-value tag (or put the - symbol if not available). I will then call it every some seconds:

setInterval (function autoRefresh() {
    /* refresh all tiles */
    $('ul[data-ajax-source]').each(function () {
        init_tile($(this));
    });
}, 30000);

This link looks interesting if I want to build a more professional and reusable plugin: Basic Plugin Creation

¡Hasta pronto!

Shared Recordset Definition

I think that the modules I developed for Sentosa Autoforms are quite elegant and flexible (expecially the Sentosa::SQL module, and the DataDatables and JSON modules) so I decided to reuse them! However I don't like the fact that Sentosa Autoforms is all driven by database data.. while it's sometimes very convenient, I don't like the layer of complexity that it adds.

So I started to work on it, trying to figure out a simpler solution!

First of all, I needed to store all recordset information on a variable, shared to all components. The hashref recordset goes to the Base.mp pure perl component:

my $recordset = {
  # Allarms
  "alarms" => {
    description => 'Alarms',
    connection => { db => 'dbi:Pg:dbname=dbname;host=10.10.10.10', username => 'myusername', password => 'mypassword' },
    source => "alarms",
    pk => 'id',
    columns => [
        { col => 'paziente',                 caption => 'Paziente', type => 'text', 'link-id' => '4' },
        { col => 'data_nascita',             caption => 'Data Nasc', type => 'text' },
        { col => 'dataora',                  caption => 'Data/ora PS', type => 'text' },
        { col => 'osp_ps_priorita_ingresso', caption => 'Priorità', type => 'text' },
        { col => 'link_fascicolo',           caption => 'Fascicolo', type => 'hidden' }
      ],
    json => 'json/alarms.json'
  },
}

Pretty elegant! Also I can use all kinds of Perl stuff to make it more tidy or more compact (e.g. I can specify a connections hash_ref, and I can calculate the array_ref columns somehow.. also, Sentosa has to process every query every time we access a recordset, while with this systems I can pre-calculate all queries at runtime the first time we access it).

How can I share this recordset data to all components? I can specify a method at the end of the Base.mp component:

method getrecordset($rs) {
  return $recordset->{$rs};
}

and then the default handler inside the json directory can be just like this:

<%flags>
extends => '../Base.mp';
</%flags>
%class
  has '_id';
  has '_app';

  has 'iDisplayStart';
  has 'iDisplayLength';
  has 'iColumns';

  has 'sEcho';
</%class>
<%init>
  my ($recordset_name, $ext) = $m->path_info =~ /(.*)(\.json)$/;
  if (! $.getrecordset($recordset_name)) {
    $m->not_found();
  }
</%init>
<&
  ../query-data-widget.mi,
    obj => {
      source => $.getrecordset($recordset_name)->{source},
      pk     => $.getrecordset($recordset_name)->{pk},
      db     => $.getrecordset($recordset_name)->{connection}->{db},
      name   => 'allarmi_osp_ricovero',
      description => $.getrecordset($recordset_name)->{description},
      username => $.getrecordset($recordset_name)->{connection}->{username},
      password => $.getrecordset($recordset_name)->{connection}->{password}
    },
    columns => $.getrecordset($recordset_name)->{columns},

    iDisplayStart => $.iDisplayStart,
    iDisplayLength => $.iDisplayLength,
    iColumns => $.iColumns,
    sEcho => $.sEcho,
    searchArgs => $.args
&>

it will inherit only from the Base.mp (no html, only perl!) ... and yes, I know this is a little ugly and not too elegant, but at least I can use the query-data-widget (and the query-widget as well) without major updates. I will work on making it better :)

Ah only one thing has to be updated! instead of working on the $.columns object I figured out that I have to work on a local copy of the object:

    use Clone 'clone';
    my $local_columns = clone($.columns);

otherwise, everytime I modify the columns object to add a temporary filter, the next time the filter is still there - because it's a hash_ref!

To call the query widget I use this:

<&
  query-widget.mi,
    query => {
      id => 'osp-ps',
      json => $.getrecordset($recordset_name)->{json},
      description => $.getrecordset($recordset_name)->{description},
      pk => $.getrecordset($recordset_name)->{pk},
      columns => $.getrecordset($recordset_name)->{columns},
      params => { 'table_link'  => undef, 'hide_title'  => 1, 'hide_top'    => 1, 'hide_bottom' => 0 }
    }
&>

Well this environment is much more comfortable, I think I can add plenty of improvements soon, and I think I can write a good manual of how to use those components. See you soon!

SQL Markdown Builder

I like text editors, especially Sublime Text. And I like to work at the command line (on Linux, on Mac... but even on Windows 10 it has become very nice).

So it's pretty normal that everything I write is in Markdown syntax!

Since I work every day with SQL, and every day I have to prepare quick reports, extract some data, share some tables, share some rows... I needed a tool to run a SQL query against a database that returns a table in Markdown format!

This way I can easily copy & paste to a new mail, and format it nicely and professionally with markdown-here, quickly and without becoming crazy.

So I quickly wrote this tool and I called SQL Markdown Builder because it can easily be integrated with Sublime Text, even if it is not a native plugin.

Yes I know this is a little off topic from Mason and Sentosa, but this tool is written in Perl and... I included it in Sentosa anyway! So let's start!

Getting Started

Make sure you have installed perl, File::Slurp, Getopt::Long, DBI, and the DBD libraries for your database:

cpanm File::Slurp
cpanm Getopt::Long
cpanm DBI
cpanm DBD::SQLite
cpanm DBD::Pg
cpanm DBD::mysql
...

Run a query

Once everything is installed, you can write a single query, or more queries separated by a ; in a .SQL text file:

drop table if exists gardens;

create table gardens (
    id integer primary key,
    name varchar(100),
    city varchar(100)
);

insert into gardens (name, city) values
('Gardens By The Bay', 'Singapore'), ('Hyde Park', 'London'),
('Central Park', 'New York'), ('Villa Borghese', 'Rome'),
('Princes Street Gardens','Edinburgh');

select * from gardens;

and you can run your query file at the command line:

perl sqlbuild.pl -c dbi:SQLite:dbname=test.sqlite3 -s query.sql

the connection string is in the DBI format, this example is for SQLite so we don't need to specify a username or a password.

SQL Markdown Builder will execute every single query in sequence against the specified database. If the query is an INSERT or an UPDATE query, it will return '0 rows', otherwise it will return the results in Markdown format (nicely aligned):

0 rows
0 rows
0 rows

id | name                   | city
---|------------------------|----------
1  | Gardens By The Bay     | Singapore
2  | Hyde Park              | London
3  | Central Park           | New York
4  | Villa Borghese         | Rome
5  | Princes Street Gardens | Edinburgh

If some columns become too big, you can specify the maximum size of a column with -mw parameter (or use -h to see all parameters).

Instead of using the command line, you can also specify all connection strings, usernames, passwords inside the .SQL file itself:

/*
  conn="dbi:SQLite:dbname=test.sqlite3"
  username=""
  password=""
*/

This is very handy but not too secure (other users might peek inside your files, and also updating a password might become complicated).

Integration with Sublime Text

This is for Windows, but Linux and OSX will be very similar.

Just get the provided file Sql-mk-build.sublime-build, update the working_dir:

{
    "cmd": ["perl", "sqlbuild.pl", "-s", "$file" ],
    "working_dir": "c:\\GitHub\\Sql-mk-builder\\"
    "selector": "*.sql"
}

and move it to the build directoy:

C:\Users\YOURUSERNAMEHERE\AppData\Roaming\Sublime Text 3\Packages\User

then you can edit your .SQL files with Sublime Text, and see the results using CTRL+B.

Happy SQL & Markdown!

Systemctl start sentosa.service

I just started to publish my Sentosa web portal and users of my company are now starting to use it. Great!

I wanted to add a service on my CentOS server and I wanted to manage it with Systemd.

First I created a /etc/systemd/system/sentosa.service file that contains:

[Unit]
Description=Sentosa Autoforms
After=network.target

[Service]
ExecStart=/usr/local/bin/plackup -E production --port 5001 --access-log /var/www/apps/sentosa/logs/access.log /var/www/apps/sentosa/bin/app.psgi

the app.psgi is the standard file from GitHub, I just disabled the debug mode.

Now I can start, restart, stop my service with:

systemctl start sentosa.service
systemctl restart sentosa.service
systemctl stop sentosa.service

And I can monitor the tail of the logs with:

journalctl -u sentosa.service -f

DB.pm Library

Hello, I'm finally back! Yes not much posts lately, but lots of coding - it's a lot considering that I'm working full time and that this is only a side project on my spare time.

After some previous attempts, I decided that I had to write a library to manage queries, to apply filters and searches, to move to the first/last/previous/next record, and to update and insert data.

I finally came out with DB.pm library, and even if it still needs to be improved I'm very proud of how small, elegant and clean it is!

I might rename it to Sentosa::SQL as I might reuse it on other projects as well.

Syntax

You need to define a $columns array reference as the following:

my $columns = [
  { col => 'id', 'pk' => 1},
  { col => 'name'},
  { col => 'surname'}
];

where id is the primary key, and then you have to call selectQuery and get a hash reference like this:

my $q = Sentosa::Db::selectQuery(
  'mytable',
  $columns,
  'ASC',
  undef,
  0, #offset
  10, #number of records
  'SQLite'
);

this will return three queries and three array references like below:

  print $q->{query}, "\n";
  print "(".join(',', @{$q->{query_data}}).")\n";

  print $q->{query_search}, "\n";
  print "(".join(',', @{$q->{query_search_data}}).")\n";

  print $q->{query_limit}, "\n";
  print "(".join(',', @{$q->{query_limit_data}}).")\n";

yes I could just call the same function thrice with different parameters (that would make the library even more elegant), but at the moment I have good reasons to call it once, but I might change my mind in a near future.

  • query: is the query, with a first level filter
  • query_search: is the query with a first filter and second level search filter
  • query_limit: is the query with a first level filter and a second level search filter, and also a limit on the number of rows (useful for pagination)

Filters

There are two levels of filters, a main filter that is applied to all of the queries, and an additional search filter that is applied only to query_search and query_limit.

This could be useful because a main filter can be applied to a table, but the user can search for some records within the already filtered table.

For example, many users could have records in the same table:

ID User Song
1 1 AC-DC - Ride On.mp3
2 1 Metallica - Enter Sandman.mp3
3 2 The Sweet - Action.mp3
4 2 Sixx::AM - Life Is Beautiful.mp3
5 2 Metallica - Metal Militia.mp3

We can filter the previous table for each user, then the user can apply an additional filter:

my $columns = [
  { col => 'id', 'pk' => 1},
  { col => 'user', 'filter' => 1},
  { col => 'song', 'search' => 'Metallica', 'searchcriteria' => 'SUB'}
];

Global variable $dbh

The name of my project is "Sentosa AutoForms", and it is going to be driven by a SQL database. I'm using SQLite but it can be changed at a later time to MySQL or Postgresql.

Let's create my new project:

poet new Sentosa

cd Sentosa

and let's create our SQLite database. The schema goes on the db/schema.sql file:

create table if not exists af_info (
      id integer primary key autoincrement,
      attribute string not null,
      value string not null
    );

insert into af_info (attribute, value) values
('name', 'Sentosa AutoForms'),
('version', '0.01');

and the actual database data goes to data/sentosa.db:

sqlite3 -batch data/sentosa.db < db/schema.sql

This is how I would access this DB with a standard Perl application (using the DBI module):

{% raw %}
#!/usr/bin/perl

use strict;
use warnings;
use DBI;

my $dbh = DBI->connect(          
    'dbi:SQLite:dbname=../data/sentosa.db',
    '',                          
    '',                          
    { RaiseError => 1 },         
) or die $DBI::errstr;

my $sth = $dbh->prepare('SELECT value FROM af_info WHERE attribute="name"');
$sth->execute();

my $name = $sth->fetch();

print @$name;
print "\n";

$sth->finish();
$dbh->disconnect();
{% endraw %}

and this is how I am connecting to it in my web application:

{% raw %}
package Sentosa::Import;
use Poet::Moose;
extends 'Poet::Import';

use DBI;

method provide_var_dbh ($caller) {
  return DBI->connect(          
    'dbi:SQLite:dbname=data/sentosa.db',
    '',                          
    '',                          
    { RaiseError => 1 },         
  ) or die $DBI::errstr;
}
1;
{% endraw %}

and this is how I'm using it on my component index.mc:

{% raw %}
<%class>
use Poet qw($dbh);
</%class>
<% $.title %>
<%init>
my $sth = $dbh->prepare('SELECT value FROM af_info WHERE attribute="name"');
$sth->execute();

my $name = $sth->fetch();

$.title("Welcome to @$name");
</%init>
{% endraw %}

True Global Variable for Mason in Poet

A few days ago, while I was roaming around Singapore, I offered a bounty (twice) on an already existing question on StackOverflow Global Variable mason2 in Poet where the poster was asking how to use global variables in Mason. And I got a very nice and useful answer :)

Here I am describing how to get a true global and persistent variable. The content of a true global and persistent variable is preserved between requests.

Has your web server 10 different threads that answer HTTP requests? Then you'll end up having 10 different variables. Has your web server 1000 threads? Well... you got the idea!

But what's the proper use of such global variables? Any thread can potentially serve any request, so we cannot predict which server is going to answer which request. Private informations doesn't have to go here.

But most web applications are driven by some datatabase, and connecting to a database has cost in terms of performance. Since the database won't (usually) change between requests why do we have to establish the same database connection over and over again?

Actually, we don't have to: we can define a global variable $dbh whose value is a valid database handler, which will be preserved between requests. This database handler value will born with the thread and will die with the thread!

Oh but we still have to be careful since the handler could have been valid at the time of the creation of the thread, but then something bad could have happened (e.g. a timeout could have occoured, or some evil DBA might had killed your connection, just for the sake of it). Somehow we'll have to manage this.

Okay now the fun part. Please read Poet::Import and the awarded answer which I'm going to use as a reference, and then let's do some coding!

Global Variable Example

# generate app Myapp
poet new Myapp
cd Myapp

add a class Myapp::Import, here's where we have to define our global variables:

vi lib/Myapp/Import.pm

and then let's add some code:

package Myapp::Import;
use Poet::Moose;
extends 'Poet::Import';

# create some variable
has 'mytemp' => (is => 'ro', default => 'my temp value');

method provide_var_mytemp ($caller) {
    return $self->mytemp;
}
1;

then we can test our global variable in our components, let's print its value on comps/index.mc:

<%class>
use Poet qw($mytemp);
</%class>
I got this <% $mytemp %> variable.

Let's see how to store a database handler, on my next post!